
Zhenyang Cai
FreedomAI CTO
Multimodal medical model R&D
- PhD candidate, The Chinese University of Hong Kong, Shenzhen
- Contributor to HuatuoGPT-o1, DentalGPT and other models
- First-author papers at NeurIPS and ACL
Biography
Zhenyang Cai is the CTO of FreedomAI, leading multimodal medical model R&D while pursuing a PhD at The Chinese University of Hong Kong, Shenzhen.
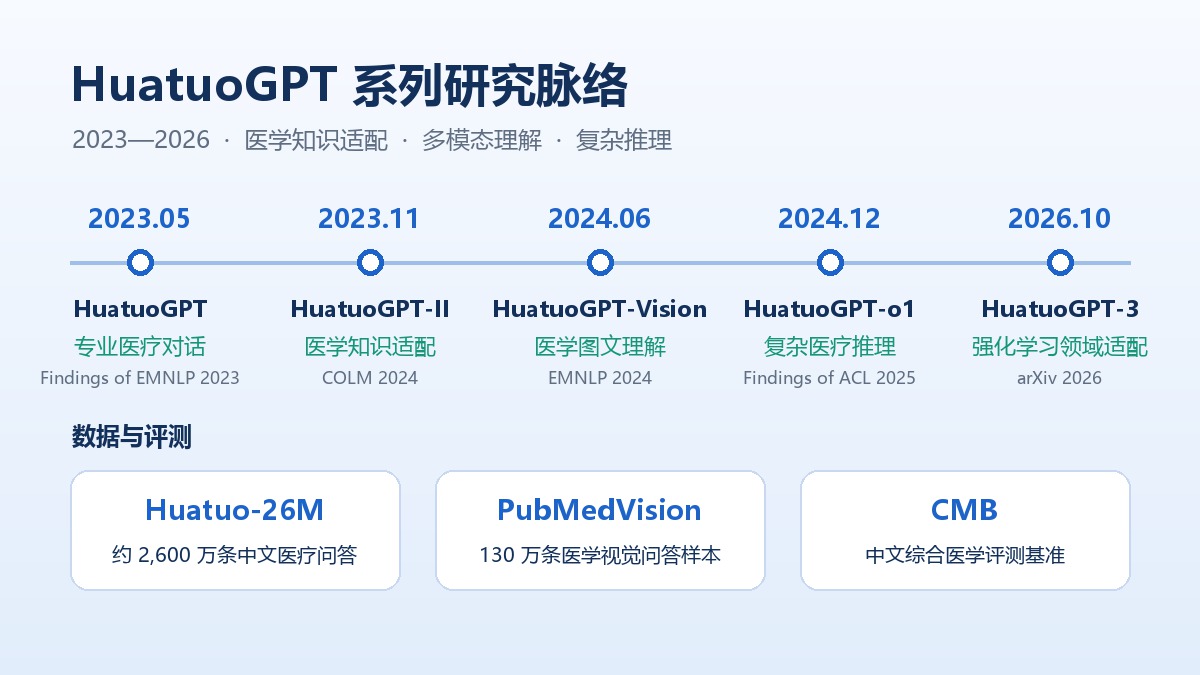
He contributed to medical large models including HuatuoGPT-Vision and HuatuoGPT-o1 (second author), and is first or co-first author of the dental multimodal large model DentalGPT (Findings of ACL 2026), the multinational dental benchmark GlobalDentBench, a study of compositional generalization in medical imaging (ACL 2025), native alignment in Arabic LLM pre-training (NeurIPS 2024) and the traditional Chinese medicine multimodal model ShizhenGPT (Findings of EMNLP 2026).
In 2026, the HuatuoGPT-Vision-2 paper he contributed to was selected as a NeurIPS 2026 Oral, and the pathology foundation model CMD and the microscopic-world benchmark MicroVerse were published at NeurIPS 2026 and ICLR 2026. As of November 2026, his papers have 1,168 citations on Google Scholar, with an h-index of 9.
Selected publications 21
Selected publications; see Google Scholar for the full list.
2026
- Incentivizing Medical Vision Capabilities from Large-Scale Multimodal Pre-training
- MedIGen: Reliable Medical Illustration Generation via Interleaved Introspective Reasoning
- Beyond ViT Tokens: Masked-Diffusion Pretrained Convolutional Pathology Foundation Model for Cell-Level Dense Prediction
- MicroVerse: A Preliminary Exploration Toward a Micro-World Simulation
- DentalGPT: Incentivizing Multimodal Reasoning in Dentistry
- GlobalDentBench: A Multinational Benchmark for Evaluating LLM Clinical Reasoning in Dentistry with Expert Calibration
- Agentifying Patient Dynamics within LLMs through Interacting with Clinical World Model
- ShizhenGPT: Towards Multimodal LLMs for Traditional Chinese Medicine
- Towards a Radiologist Imitation Framework for 3D CT Diagnosis with Multimodal LLMs
- To What Extent Do Token-Level Representations from Pathology Foundation Models Improve Dense Prediction?
- DeCo-MIL: Debiased Counterfactual Reasoning for Long-Tailed Whole Slide Image Analysis
2025
- Exploring Compositional Generalization of Multimodal LLMs for Medical Imaging
- Towards Medical Complex Reasoning with LLMs through Medical Verifiable Problems
- LongLLaVA: Scaling Multi-modal LLMs to 1000 Images Efficiently via a Hybrid Architecture
- ShareGPT-4o-Image: Aligning Multimodal Models with GPT-4o-Level Image Generation
- WaveMind: Towards a Conversational EEG Foundation Model Aligned to Textual and Visual Modalities
- MedGen: Unlocking Medical Video Generation by Scaling Granularly-annotated Medical Videos
- Can Multimodal LLMs See Materials Clearly? A Multimodal Benchmark on Materials Characterization
Related News
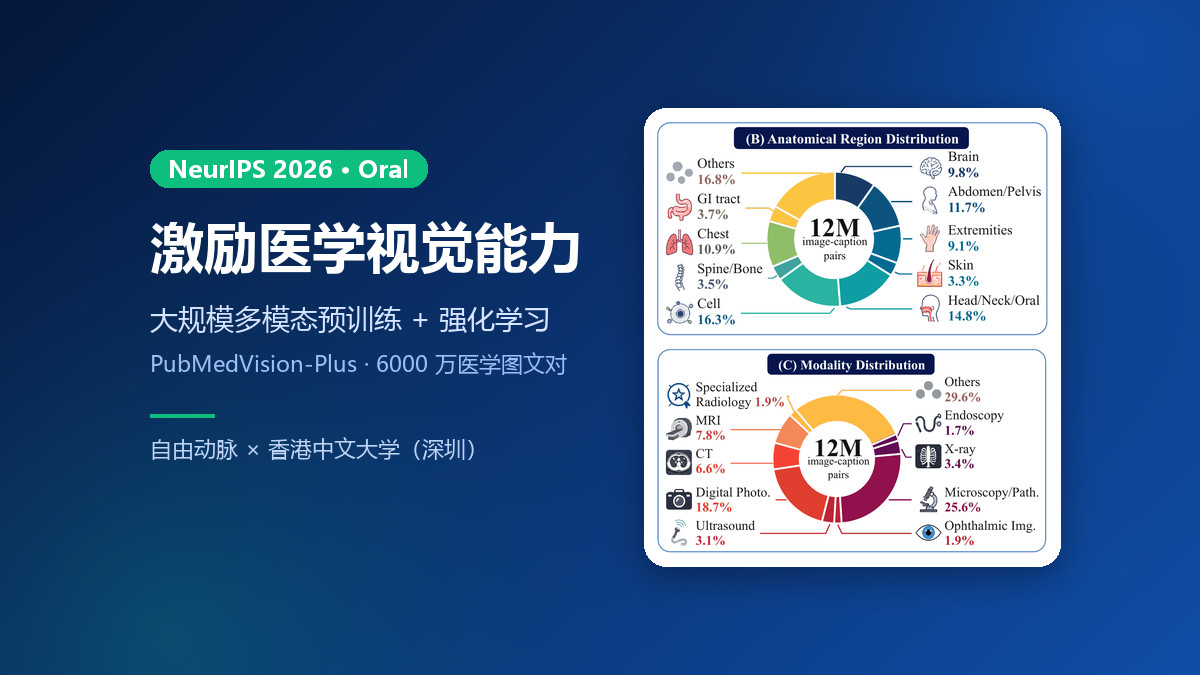
NeurIPS 2026 Oral | FreedomAI and The Chinese University of Hong Kong, Shenzhen release a medical multimodal large model that uses reinforcement learning to unlock medical vision capabilities
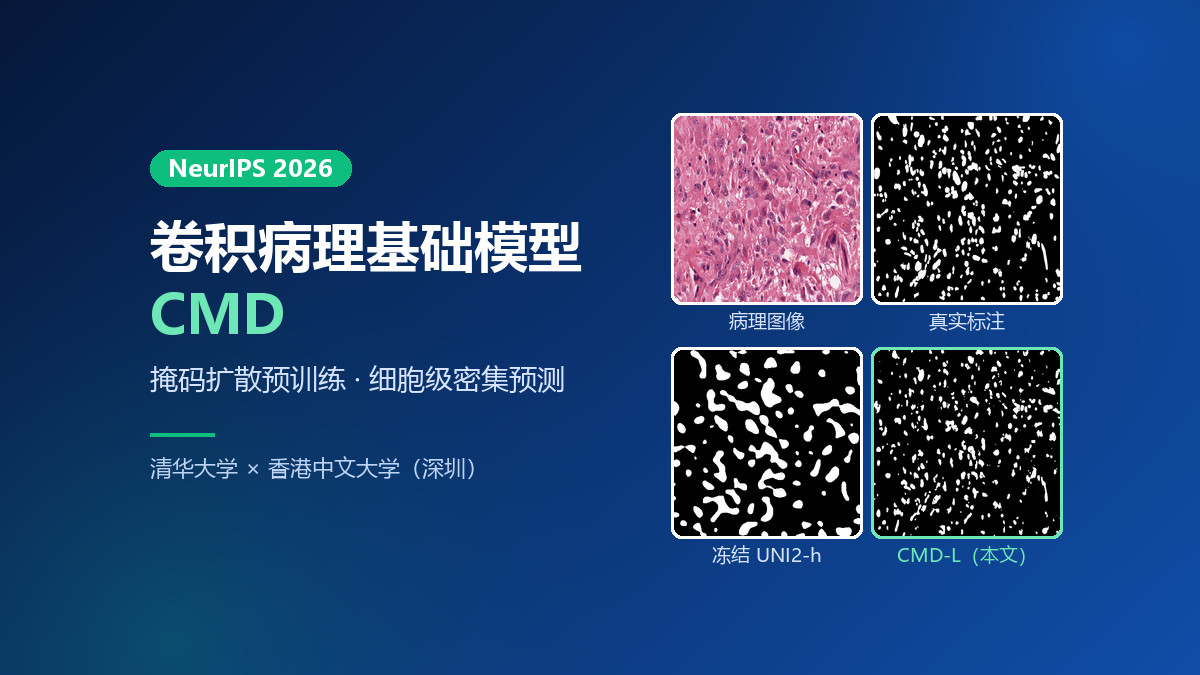
NeurIPS 2026 | Co-authored by FreedomAI CTO Zhenyang Cai: a convolutional pathology foundation model trains only 7 million parameters and beats ViT pathology models at cell segmentation
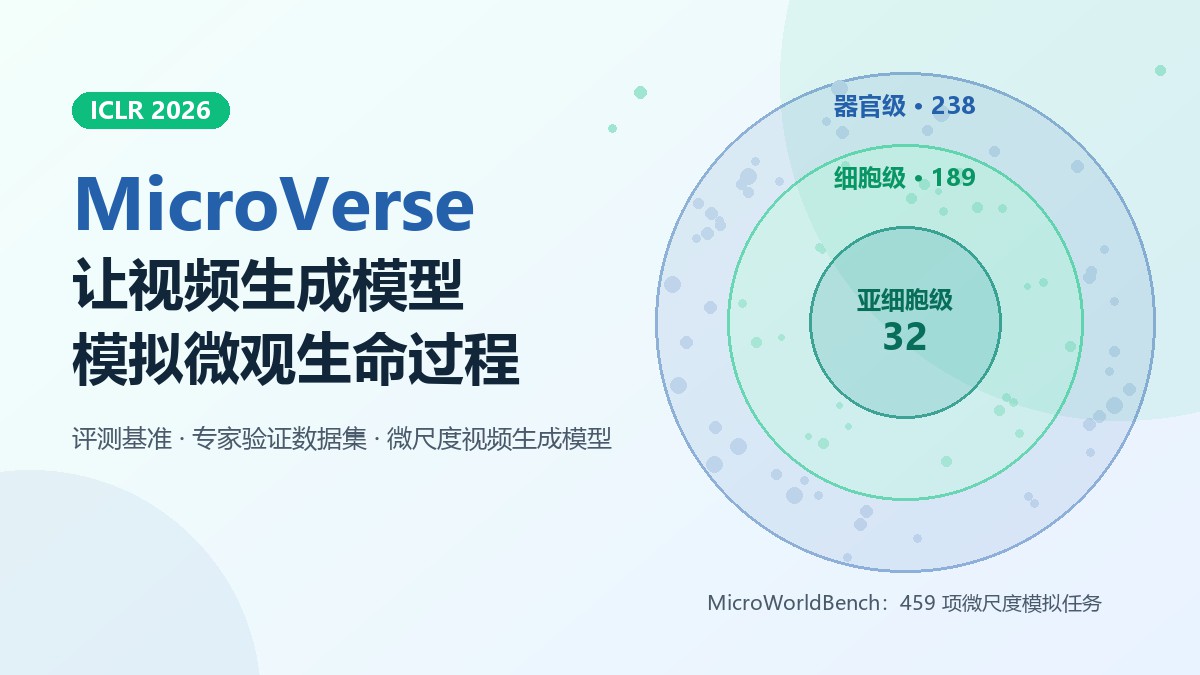
ICLR 2026 | Co-authored by FreedomAI CTO Zhenyang Cai, MicroVerse uses 459 tasks to expose video models' "micro-scale blind spots"
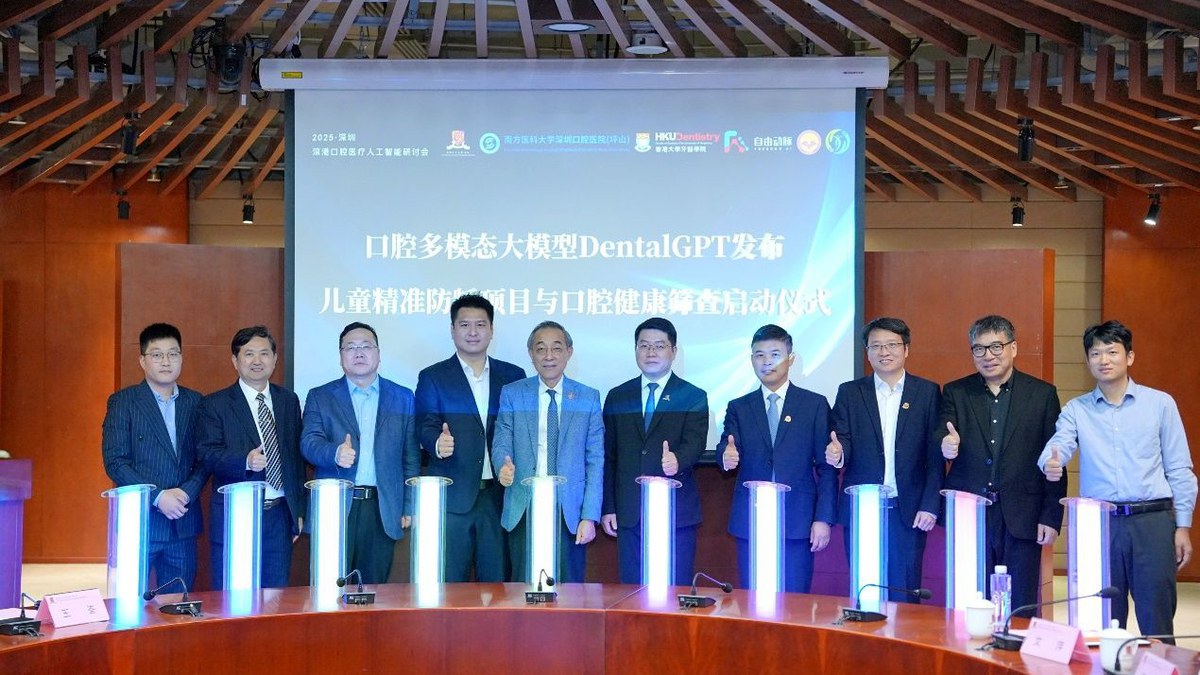
ACL 2026 Findings | FreedomAI, CUHK-Shenzhen and partners release DentalGPT, a multimodal oral-health large model: 7B parameters, higher average accuracy than GPT-5 on five dental benchmarks
 Jianquan Li
 Junjie Zhao
 Xiangyi Feng
 Zhiyi Zhang
 Junwen Wang
 Benyou Wang